Bioinfo Agent.
The agent uses three knowledge sources. The first is a curated corpus of about 31,000 BioRxiv bioinformatics preprints (RAG). The second is an in-house PubMed MCP server that searches peer-reviewed papers live. The third is an in-house UniProt MCP server that looks up proteins, genes and structures. Ask it a question
For example, "explain genome assembly like I'm 5" or "find recent papers on CRISPR base editing"
Powered by Claude Haiku 5.5 · Voyage AI embeddings · pgvector · FastMCP · Google Cloud
What
Bioinfo Agent is a proof of concept. It is an AI research agent for bioinformatics. It uses three knowledge sources that complement each other. A curated corpus of BioRxiv preprints gives depth on niche topics in computational biology. A live PubMed MCP server keeps the answers current with peer-reviewed literature. A live UniProt MCP server gives facts about proteins, genes and their structures. Claude Haiku 5.5 is the agent. For each question, it decides which sources to use, and in what combination
Question → Answer flow
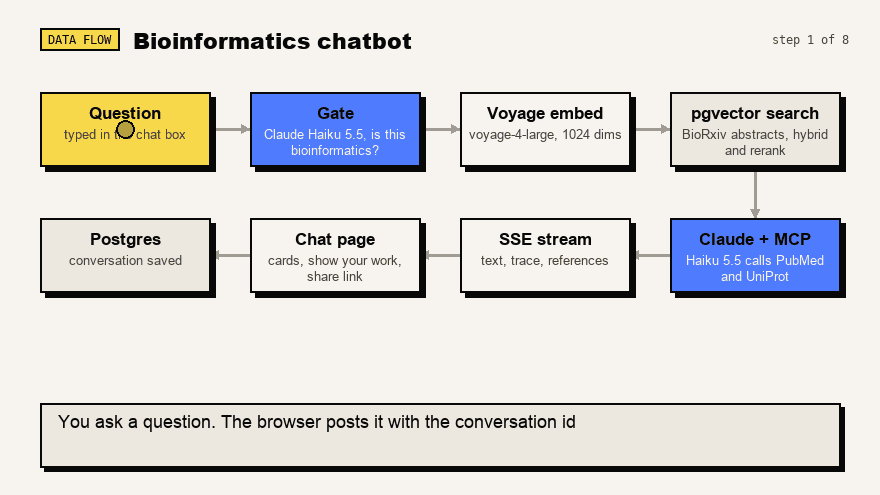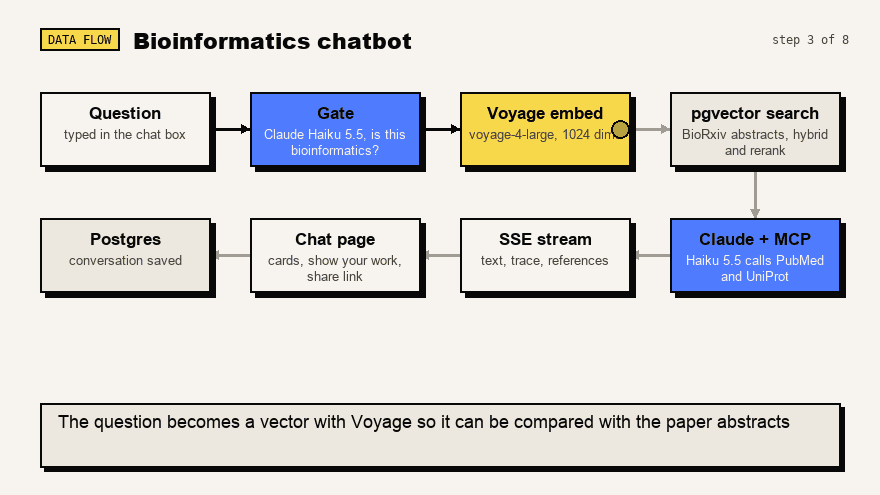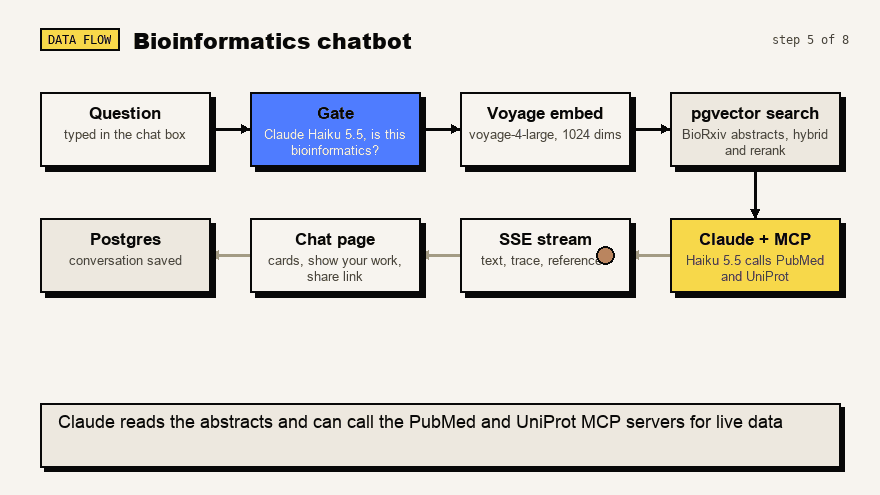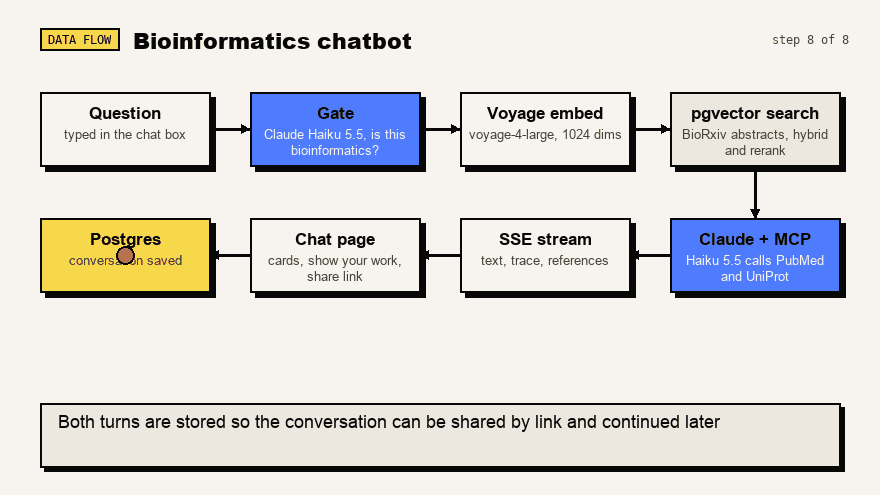
- A fast Claude Haiku decision call first checks that the question is about bioinformatics before any search runs. Anything else gets a polite refusal
- Voyage AI embeds your question (
voyage-4-large, 1024 dimensions) - A hybrid search runs against about 31,000 BioRxiv abstracts in Cloud SQL. A pgvector cosine search keeps the papers within a relevance threshold. A Postgres full text search finds the papers that use your words. Reciprocal rank fusion joins the two lists
- The Voyage AI reranker (
rerank-2.5-lite) reads the abstracts and keeps the best 5 - Claude receives your question, the BioRxiv context and earlier PubMed results (for a follow-up question). Then it decides whether to call the PubMed or UniProt MCP servers
- If Claude calls a server, GCP service-to-service identity tokens authenticate the request. The request then goes to a FastMCP server on Cloud Run. The PubMed server queries the NCBI E-utilities API and the UniProt server queries the UniProt REST API
- Claude writes a response that cites BioRxiv papers by number, like [2], and PubMed papers by author and year. The server streams it back as Server-Sent Events (SSE), and the browser shows it word by word
GCP architecture
| Service | Role |
|---|---|
| Cloud Run (Django) | The main web app. It handles requests, RAG retrieval and Claude streaming |
| Cloud Run (FastMCP) | The in-house PubMed MCP server. It wraps NCBI E-utilities and exposes search_pubmed, get_paper_metadata and find_related_papers
|
| Cloud Run (FastMCP) | The in-house UniProt MCP server. It wraps the UniProt REST API and exposes search_proteins, get_protein_by_accession, find_proteins_by_gene and get_structures_for_protein |
| Cloud SQL (PostgreSQL) | Stores BioRxiv paper embeddings via the pgvector extension |
| Secret Manager | Stores API keys (Anthropic, Voyage AI) |
| Artifact Registry + Cloud Build | Container image storage and CI/CD pipeline |
v1 → v2 → v3 → v4
| Agent v1 (2023) | Agent v2 (2025) | Agent v3 (2026) | Agent v4 (2026) | |
|---|---|---|---|---|
| LLM | Claude Sonnet 2.x | Claude Sonnet 4.6 | Claude Sonnet 4.6 | Claude Haiku 5.5 |
| Embeddings | OpenAI ada-002 | Voyage AI voyage-3-large | Voyage AI voyage-4-large | Voyage AI voyage-4-large |
| Vector DB | Pinecone (managed) | pgvector on Cloud SQL | pgvector on Cloud SQL | pgvector on Cloud SQL |
| Chat state | Global Python list (shared) | Django sessions (per-user cookie) | Per-page-load UUID, saved in Postgres for 30 days with a share link | As v3, and each answer keeps its rating |
| Knowledge sources | BioRxiv RAG only | BioRxiv RAG only | BioRxiv RAG + live PubMed MCP (agent decides) | BioRxiv RAG + live PubMed and UniProt MCP (agent decides) |
| PubMed tools | None | None | search, get metadata by PMID, find related papers | search, get metadata by PMID, find related papers |
| MCP auth | None | None | GCP service-to-service identity tokens | GCP service-to-service identity tokens |
| References | None | Top 5 BioRxiv papers per response | BioRxiv preprints + PubMed live results, badged by source | Numbered BioRxiv cards + PubMed and UniProt results, badged by source |
| Citations | None | None | Author and year in the text | Numbered [n] citations. A click scrolls to the matching card |
| Feedback | None | None | None | Useful and Not useful buttons under each answer |
| Paper map | None | None | None | Open the agent from a paper on the map. That paper goes first as [1] |
Why
The aim is to show that an AI agent with structured retrieval and live tools can make a literature review much faster. The BioRxiv corpus alone is about 29 years of reading at 3 papers a day. PubMed adds tens of millions of peer-reviewed records, which the agent searches on demand